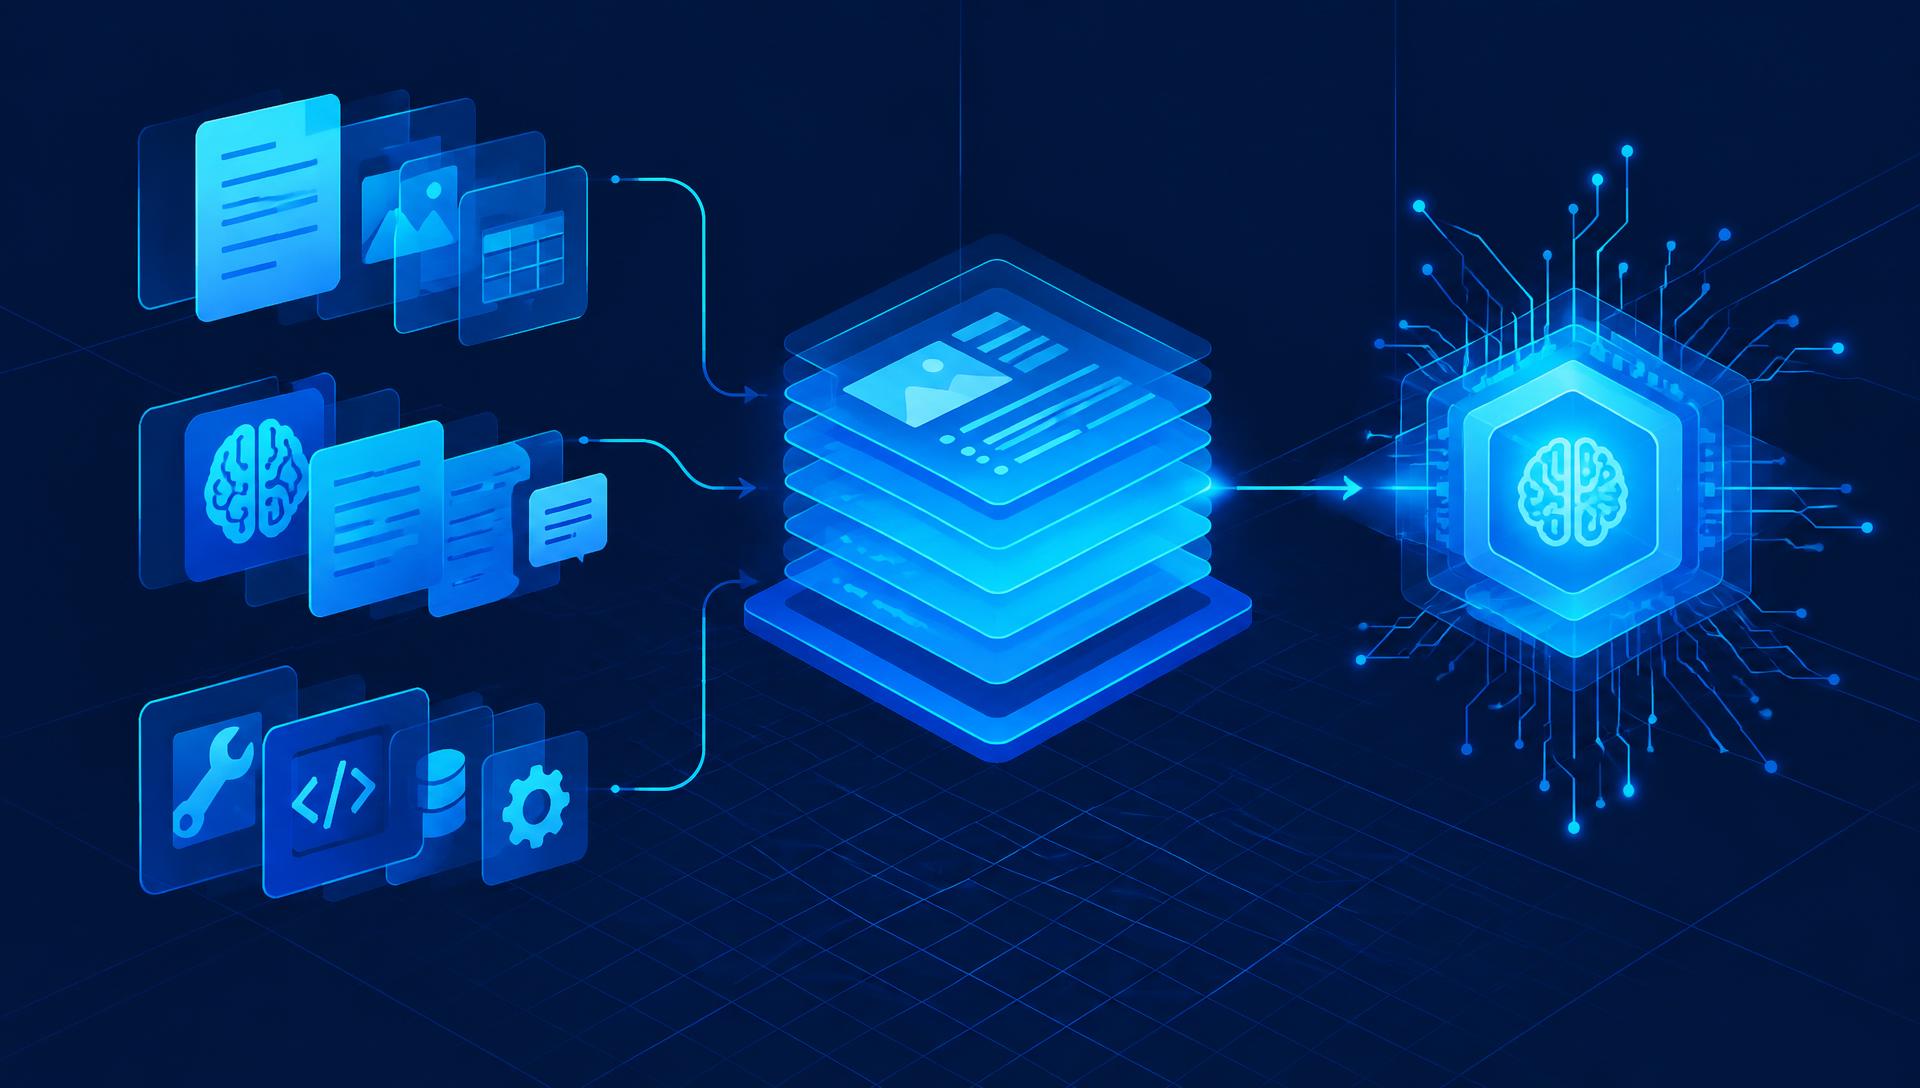
Two years ago the hot skill was prompt engineering - crafting the magic incantation that made a model behave. In 2026, the teams shipping reliable AI barely talk about prompts. They talk about context: the full package of instructions, memory, retrieved knowledge, tool results and constraints assembled for every single request. The model is the same for everyone. The context is your competitive advantage.
From prompts to context
Prompt engineering assumed the model's input was a sentence you could perfect. Production AI killed that assumption. A support agent's answer depends on the customer's history, the current policy version, the order system's response and the tone rules for that region - none of which fit in a clever sentence. The question shifted from "what do we tell the model?" to "what does the model need to see, right now, for this user, for this task?" That is an engineering problem, with pipelines, budgets and tests - not a writing exercise.
The evidence is in the failure patterns. When an enterprise AI feature misbehaves, the cause is almost never a badly worded instruction. It is stale memory, a missing document, a tool result pasted in the wrong format, or a context window stuffed with so much material that the model's attention thins to mush. All context problems.
The six-layer context stack
Every production AI request we build assembles context in six layers. Thinking in layers matters because each has its own freshness, cost and failure profile:
- 01System instructionsRole, tone, hard constraints and refusal rules. Stable, versioned like code, reviewed like policy. Changed rarely, tested always.
- 02Session stateWhat has happened in this conversation or workflow so far. The difference between an assistant that remembers step two and one that asks again.
- 03Long-term memoryFacts learned about the user or account across sessions - preferences, history, past decisions. The most valuable and most dangerous layer.
- 04Retrieved knowledgeDocuments, tickets, policies and records pulled fresh per query. The RAG layer - see our RAG vs long-context report for the architecture decision.
- 05Tool resultsLive data from APIs and systems of record: order status, account balance, inventory. Formatted for the model, not copied raw from the API.
- 06Output contractThe schema, format and length the answer must take. Defined as structure, not begging, so downstream systems can rely on it.
The model is a commodity. The context stack - what you assemble, from where, with what freshness and permissions - is the product.
Memory: the layer everyone gets wrong
Memory is where demos become products and where products become liabilities. The naive version - "remember everything the user ever said" - produces assistants that confidently act on year-old preferences and surface facts the user would rather forget. The engineered version treats memory like a database, not a transcript: facts are extracted, typed, timestamped, given a confidence and an expiry, and written back only when they clear a relevance bar. Users can see and delete what is stored about them, which is increasingly a regulatory expectation, not a courtesy.
The design questions that matter: what is worth remembering (preferences and decisions, not chit-chat), when to write (after confirmed outcomes, not mid-conversation guesses), and when to forget (expiry, contradiction, user request). Get these right and the assistant feels uncannily competent. Get them wrong and it feels like a stalker with a filing cabinet.
The failure modes we keep seeing
Four context failures account for most of the enterprise AI rescues we are called into. First, context rot: the window fills with accumulated history until the model loses the thread - the fix is compaction and summarisation, not a bigger window. Second, stale retrieval: the index serves last quarter's policy because nobody owns freshness - the fix is a knowledge owner with an update SLA, as we detail in our knowledge architecture report. Third, tool-result dumping: raw JSON API responses pasted into context, burning tokens and confusing the model - the fix is a formatting layer that translates system output into model-readable briefs. Fourth, instruction sprawl: system prompts that grew to 4,000 words of contradicting rules nobody dares delete - the fix is versioning and deletion, same as code.
The build order that works
Do not build all six layers at once. The order that survives contact with production: start with instructions and the output contract (week one - cheap, testable, immediate quality jump), then retrieval (the knowledge your answers stand on), then tool results (live data, with formatting), then session state, and only then long-term memory - last, because it is the highest-risk layer and benefits from everything before it being stable. Each layer gets its own evaluation set before the next begins. This sequencing is also how you keep the cost curve sane, which maps directly to the unit economics in our AI FinOps report.
Who owns context engineering
Context engineering sits at the intersection of backend engineering, data engineering and domain expertise, which is why it falls between chairs in most organisations. The working model we see: a platform engineer owns the assembly pipeline, a domain owner owns the knowledge and instructions, and both share an evaluation harness that fails the build when quality drops. If your AI feature has no named owner for what the model sees, that is the gap to close first - before any model upgrade, because the upgrade will not fix it.
Where RanWebs fits
We design and build context stacks on our AI engineering track: the evaluation harness first, then the six layers in the order above, with memory governance and cost controls from day one. Typical engagement: four to eight weeks from audit to a production pilot with measured answer quality.
Have an AI feature that demos well and disappoints in production? Email info@ranwebs.com or use the contact page. First call is free and goes to a senior consultant.